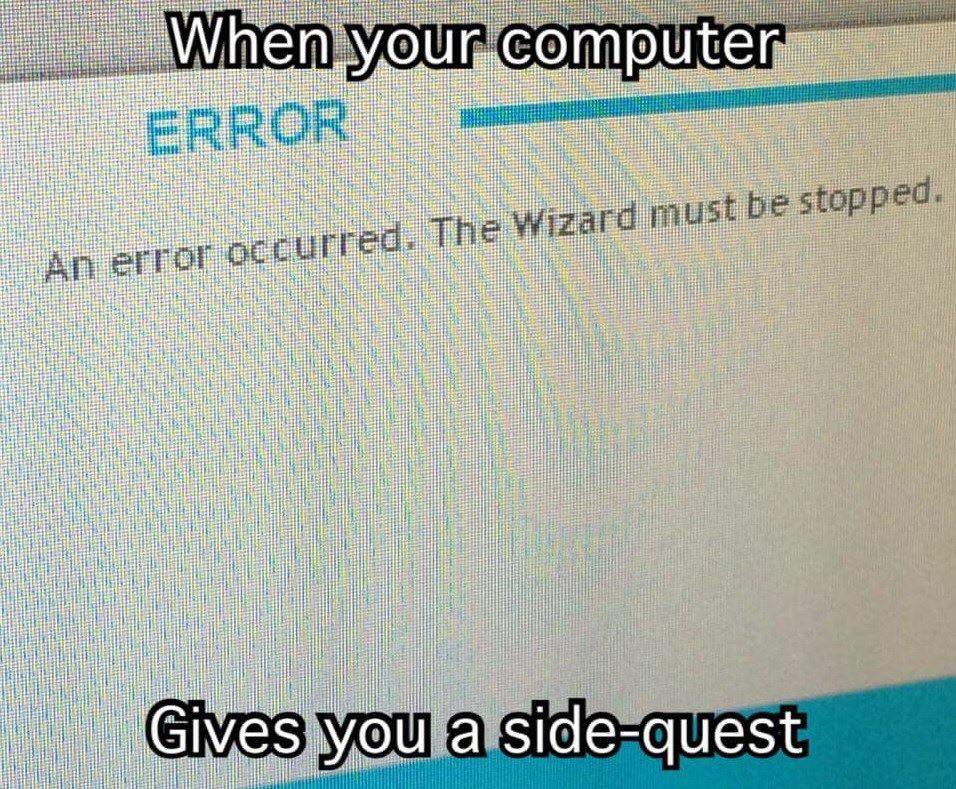
I’m sure this is old, but I had not seen it before, and it made me laugh.
7 Likes
[strokes beard]
So, my old comrade, it’s come to this, has it?
5 Likes
So we’re going to Korea next month, I suggest to Hozumi that she check whether her phone can use an eSIM. Get out of the shower and she tells me her phone has locked her out. Turns out that her phone has an option to manually activate the lock that occurs when you get the PIN wrong 10 times, and that she had for some reason activated that lock while attempting to determine whether her phone can take an eSIM (it can’t, as a simple Internet search reveals).
Looking up the details of her SIM, the only way to get the PUK code to unlock the phone that she needs for work is by calling our provider between 9:00 and 18:00. So I resolve to do that Monday morning, because she has to go to work.
But it turns out the support line is ALWAYS busy, and just responds with an automated “please try again later”.
So that’s fun. Self-inflicted, sure, but my phone doesn’t even have an option to manually lock myself out of it, so I have to wonder why hers does.
6 Likes
Also, just to keep things spicy, although the phone support usually just tells me to call back later, 1 time in 10 I’ll get through to an automated multiple-choice menu where I can get three deep into the menu before it tells me the lines are busy and I have to call back later.
After calling all day, I get through after 20 minutes on hold, to someone who eventually tells me the number I called, which is the specific number listed on the help page for this specific problem, is the wrong number, and I’ll have to call another. Only now it’s gone 18:00, so I’ll have to wait until tomorrow to try it…
9 Likes
File under “Things which make me quite angry”:
Content-Type: text/plain; charset=utf-8
Content-Transfer-Encoding: quoted-printable

Please use an email client that supports HTML.
4 Likes
It is specifically not compliant with the MIME standard: if you aren’t willing or able to provide a plain text representation, you don’t provide it; you don’t provide a stub.
4 Likes
Spent my evening figuring out if the automated scanner/hacker actually exploited the CVE they tried to abuse…
(gitea, should have patched it 2 weeks ago–I stumbled across the issue when git pull origin main failed with the weirdest error message.)
4 Likes
I spent about 4 hours tracking down what happened. I was reminded to try the “stupidly trivial” stuff first next time.
I was two weeks behind with my containers…
The attacker used the CVE on one of my (no longer) public repositories to insert a malicious hook-script. And then linked it in my global git config somehow so that it would execute when I tried to pull from any repo.
The thing that saved me was that apparently the script they were trying to execute either contained a mistake or just wasn’t applicable to my specific situation.
When I pulled I got a (fatal: protocol error: bad pack header) mistake on the commandline and something similar in my logs. Grafana was a sure winner today helping me by (1) keeping my logs when my docker compose down deleted the local copies and (2) letting me browse them in a sensible way.
The malicious hook was quickly identified and removed.
But what took me 4 hours to find was how the other repositories were linked to a file in that one repo.
The dumbest thing I did was listen to the self-confident AIs (Gemini on Perplexity and Claude.ai, Mistral I tried but Vibe had a failed update because python pip installs are so broken) as they were sure their next idea was it … they all had the wrong directories for the git config. And what found the stuff in the end was a stupid
“grep -r”
4 hours because I didn’t try the obvious thing because I kind of thought the grep was going to run forever. Okay on the way to this I did harden my containers and configurations, blocked the IP via firewall (and considered introducing a whole blocklist, for a private server a few false positives are NOTHING) etc etc.
I am usually very good at prompting but debugging my server has repeatedly failed to generate quick solutions.
Those things are so good at programming that I forget they aren’t all that great when they cannot do everything because I am not going to let any of them close to my actual infrastructure.
For a few moments there I tought I was losing my gitea setup–not the actual repo data… git is distributed for a reason, but i am using gitea as a ticket system as well and I actually host some repos on there exclusively and cloning was broken, too.
And now it’s past 1am and I am dealing with an abundance of “no sleep neurotransmitters” (aka adrenaline). Really great.
PS: sorry all the not-techies on here. I just needed to vent and send out a reminder to everyone that CVEs really do get exploited.
8 Likes
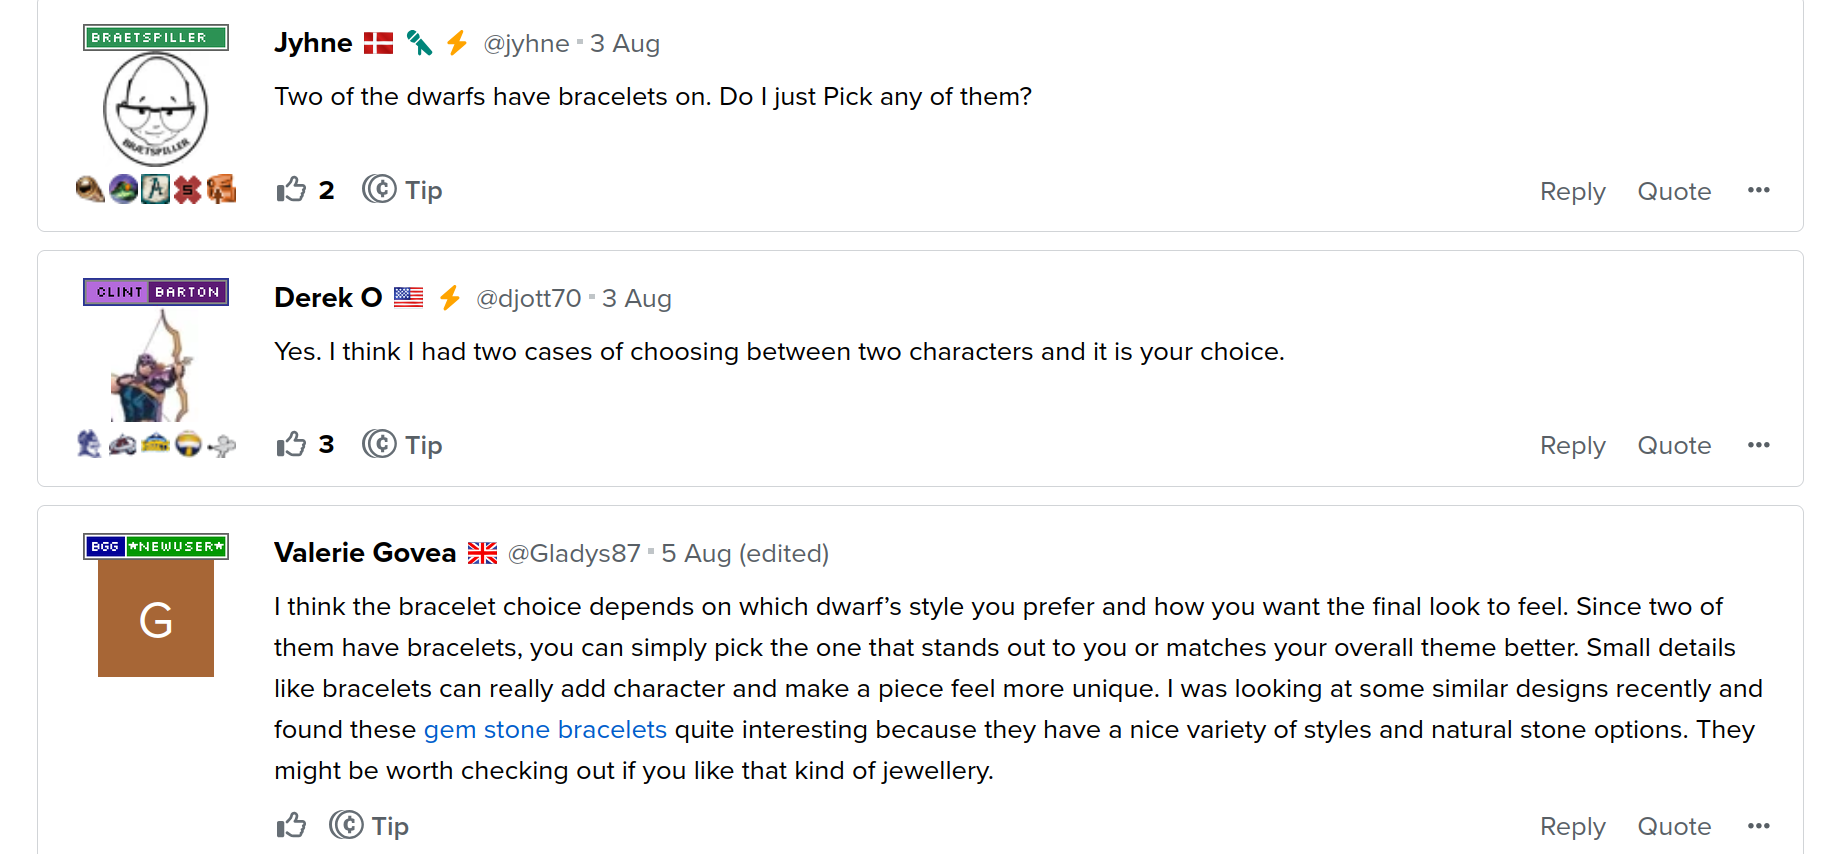
A.I. bots posting spam does have its entertaining side…
https://boardgamegeek.com/thread/3747059/bracelet-on-two-dwarfs
Spent half the evening debugging a weirdness with my s3 storage at Hetzner only to learn after 2 hours of debugging that they had 2 back-to-back hardware failures in that particular object storage and are restoring the s3 manually and … WTF?! Lucky me I am syncing everything in that storage to our NAS as well, I shut down the sync for now. But the whole point of object storage is kind of moot when stuff like this happens.
My wild assumption is that even after raising prices on servers by a lot… they are trying to run hardware longer because hardware is now prohibitively expensive.
4 Likes
Gotta keep those profit margins up!
2 Likes
It sounds like they had only mirroring? RAID configurations which tolerate multiple simultaneous failures are very well understood. Needs more hardware of course, so maybe they do support it, but only as a more expensive service?
1 Like
Certainly all they’ve ever offered me for dedicated servers is two mirrored discs, not the six or eight I’d want for a proper RAID.
2 Likes
I wonder whether, statistically, mixing discs of different ages provides better outcomes (such that failures are anticipated to happen while the rest of the array is in comparatively good nick, rather than everything getting old at the same time).
2 Likes
at least my bucket is back. I have no idea how s3 storage works. But yeah, my partner had the Raid5 when his harddrive failed after his desktop literally crashed to the floor and it ended up fine with just one harddrive needing replacement.
I have mounted the bucket locally and will (while sync is turned off) compare to the state on the NAS. At this moment everything is still present in at least one location (newest photos on mobile).
And I will finally order an external HDD to have an air-gapped copy as well.
those 100.000 photos… want protecting.
And I really really really need to dist-upgrade my server.
And so much more. I could easily spend a month doing nothing but personal IT stuff and still not be finished.
2 Likes
It does! Sadly populating a new array tends to be a matter of urgency.
1 Like
One of the shops I worked in dealt with this by incrementally replacing disks in arrays. Usually, that happened when a new one was built. Need 10 disks for it, buy 12, replace a couple in the old one. Upgrades had some of the disks replaced pushed into other arrays i they were suitable. There had been a horrible incident where an array got built with disks that all shared the same defect, and all died in quick succession. It was before my time, and it colored a lot of how they did things.
4 Likes
On “prohibitively expensive,” my employer’s capital planning was wrecked by Dell and HP server pricing rising by factors of 4.5 to 5. I’m not sure if my group is going to get any replacement servers next year; priority is going to replacing kit more than seven years old.
Company policy is to put everything in the cloud. My group resists that because of multiple data-confidentiality issues. We’re finding that the prices of powerful deskside machines have risen less than rackmount servers and are buying a few of those.
3 Likes
I (as the technical part of my organisation) resist it because every time I price it up it will cost more. We essentially run a specialised search engine, so there’s a lot of CPU use, not just a database or flat web pages.
1 Like
The push is strong everywhere to make nobody own hardware anymore and do everything in the cloud. It sucks.
5 Likes